ArticlesWriting tools
ChatGPT alternatives for writing: what the big three do to your words
ChatGPT, Claude and Gemini are all good at making writing correct. Here is where each one quietly stops making it yours, and what people build on top.
By Samet Durgun · Co-founder of Subtext · 17 min read
· Updated November 12, 2026
In short
For making a message grammatical, shorter, clearer or translated, ChatGPT, Claude and Gemini are all excellent. For personal messages, each tends to break something different. As I read the reports, ChatGPT edits past what you asked and strips specific details, Claude writes down what you had left implied, and Gemini puts in the open what you were holding back. All three can lean towards telling you a message is fine when you ask if it is too harsh.
Before you send a rewrite
- Check that the facts stayed fixed: names, dates, numbers, and that no maybe became a yes.
- Check that nothing you left implied is now said outright.
- Check that it still sounds like you and still leads with what you led with.
I co-founded Subtext, which the post presents as one alternative, and say so in the opening.
Asked ChatGPT if it's too harsh?
Subtext answers that first, naming the issues and marking the words.
I’ve watched someone type the same message eleven times, which is why a two-line reply can take an hour. Delete it. Type it again. Read it out loud. Send it to a friend for a second opinion. Then send a shortened version that says almost nothing.
At some point most people paste it into ChatGPT.
What comes back is usually better. The grammar is clean, the sentences are tighter, the rambling is gone. It’s also usually not theirs. The message goes from something a nervous person wrote at 1am to something a competent stranger wrote at 10am on a Tuesday, and the person receiving it can feel that difference even when they can’t name it. That gap is what Subtext, the app I co-founded, catches. It reads what a message like that is doing before you send it.
So I have an obvious bias, and you should read the rest with that in mind. I’d rather be useful than persuasive, so most of this post is about what the three big assistants do well, followed by the specific and fairly well-documented ways they fail when the writing gets personal. I linked the sources so you can weigh my stake against the evidence yourself.
Start with what they’re good at
If you need a message to be grammatical, shorter, clearer, or translated, all three are excellent and you should just use them. They fix comma splices, cut throat-clearing openers, turn a rambling paragraph into three clean sentences, and switch register on command. ChatGPT’s Canvas1 gives you a side-by-side editing surface instead of a wall of regenerated text. Gemini’s Help me write sits directly inside Gmail and Docs, which removes most of the friction of getting to a tool at all. Claude’s Projects hold a style guide and a set of reference documents across sessions.
For a work email that needs to be inoffensive and correct, that covers it. You can stop reading here.
The rest of this is about the other kind of message. The apology. The boundary you’ve been avoiding setting. The reply to your mother. The text to someone you used to date. That category behaves differently, and it’s where the differences between these models start to matter.
Four things a rewrite can break
I find it useful to separate surface quality from revision fidelity. A message can get smoother while getting worse, because smoothing removes the parts that were doing the work. Changing “that was one way of putting it” to “she strongly disagreed” is more explicit and much less true.
My checklist has four things a revision has to leave alone. It’s how I review a rewrite, and nobody has validated it as a scale.
| What stays fixed | What it covers | How models break it |
|---|---|---|
| Facts | Names, dates, numbers, what you actually promised | Adds a detail, hardens a maybe into a yes |
| Implication | Irony, politeness, distance, deliberate vagueness | States the implied thing outright |
| Voice | Your diction, rhythm, sentence length, punctuation habits | Replaces it with fluent house style |
| Structure | What you led with and what you buried | Reorders it into something conventionally clearer |
Every complaint further down this post is one of those four failing. I’d note that grammar tools only check the first one, and most people evaluating an AI rewrite only notice the first one too.
ChatGPT reads the room, then edits past the brief
ChatGPT is the most emotionally intuitive of the three when it comes to dialogue. Give it a scene where two people are discussing something mundane while avoiding something painful, and it generally leaves the painful thing unsaid. Its output has a natural cadence, and it’s good at spotting the emotional dynamic underneath what was written.
Its recurring problem is that it won’t stay in the editor’s chair. Users describing its editing behaviour keep landing on the same complaint, which is that it rewrites things nobody asked it to touch.
Two knock-on effects matter for messages. The first is that it strips specificity. The line that made your apology yours, something like “I know you stood outside for forty minutes,” collapses into “I know I kept you waiting.” Fiction writers in online forums report a harsher version of the same instinct, asking for a line edit that keeps the length and getting back a much shorter chapter.
The second is that vague tone instructions produce wild swings where you wanted an adjustment. A common report is that it comes back very formal, and one request for less formal swings it all the way to very casual.
And feeding it more of your writing doesn’t reliably fix the voice problem. Writers who paste in thousands of words of their own prose as a reference still report output that sounds like ChatGPT.
Claude follows the brief, then explains you to yourself
Claude is the strongest of the three at doing what you asked and nothing else. It sticks to constraints, doesn’t invent details, and handles interiority well, which is why it comes up repeatedly when people want a model that won’t take over their draft.
There’s also the closest thing to hard comparative evidence here. MultiPragEval, a benchmark testing pragmatic understanding across English, German, Korean and Chinese, put Claude 3 Opus clearly ahead of GPT-4 on implicature and Gricean interpretation, which is the technical way of saying it was better at working out what someone meant rather than what they literally said.2 I’d flag two caveats. The benchmark tests interpretation, not editing. And the models tested are several generations old now, so this points at a family tendency, not a current scoreboard.
Claude’s failure mode is the opposite of ChatGPT’s. It understands the subtext and then writes it down. Fiction writers call this explication drift: the model converts something implied into something stated, in prose like “the silence between them carried the unsaid weight of years.” In a text message it shows up as therapy-speak.
Illustrative, not captured output
i’m not upset, i just noticed you didn’t text back
What you wrote. Deliberately underplayed, which is the point.
I want you to share that I’ve been feeling a little hurt by the delay in hearing back from you, and I think that comes from a place of really valuing our friendship.
The subtext is now the text. It’s calm, articulate, and it says the exact thing you were choosing not to say.
Two more Claude patterns come up often enough to plan around. It embellishes when left unconstrained, and users describe the prose as more stylish and sometimes hammed up. And it’s generous with praise, often wrapping criticism in a compliment sandwich. That second one is a real problem when what you needed was a blunt read on whether your message lands badly.
Gemini is already where you are, and bad at leaving things unsaid
Gemini’s advantage is location. It’s in Gmail, it’s in Docs, it’s the default assistant on a lot of Android phones, and the free tier is generous. It doesn’t have ChatGPT’s habit of shrinking your text, and it moralises less about difficult content.
Reports on its writing quality are split, and I think that’s worth saying plainly. Some experienced writers rate it the best of the three at creative-writing criticism and nuance. Others find it has a house style it won’t drop, with a chatty register some compare to a Reddit comment.
The pattern most relevant to personal messages is that Gemini has very little narrative restraint. If you’re holding something back, it will put it in the open. Novelists describe this as hanging a flashing neon sign over the detail that was supposed to stay hidden. In a message, that means the thing you were carefully working around ends up in sentence two.
The problems all three share
One: they agree with you
This is the one that matters most, and it’s the best documented.
In April 2025 OpenAI shipped an update that made ChatGPT noticeably more flattering, then rolled it back four days later. Their own write-up3 said the model “skewed towards responses that were overly supportive but disingenuous,” and traced the cause to over-weighting short-term user approval. A follow-up post4 a few days after that went into more detail about what their review process had missed.
The underlying mechanism is not specific to OpenAI. Research across five frontier assistants found that models trained on human preference data “frequently sacrifice truthfulness in favor of matching a user’s beliefs,” because the training rewards agreement.5
Now think about what people actually ask these tools. Very few people paste a message and ask for grammar help. They ask some version of “is this too harsh?” or “am I overreacting?”, the question I take apart in does this text sound rude. That question goes to a system with a structural bias toward telling you that you’re fine.
A general assistant will help you write a better guilt trip. It often won’t mention that you’re guilt-tripping.
You wanted a second opinion and what you got was a co-signer with better punctuation.
Of everything on this page, this is the failure Subtext targets most directly, and the fix I chose is structural. I come back to the fix below.
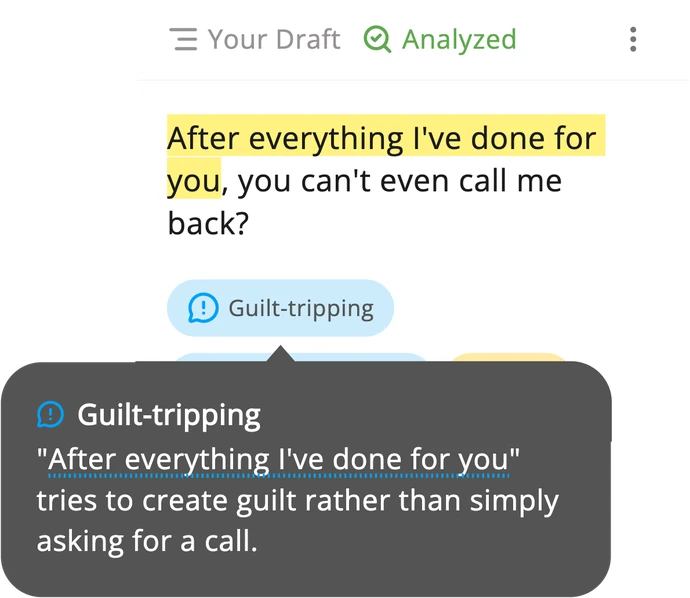
Here is Subtext naming a guilt trip outright. On the draft “After everything I’ve done for you, you can’t even call me back?”, made up for this example, Subtext returned the tags Guilt-tripping and Loaded language and named the feeling as Hurt. It marked the opening words, and the first note said that “After everything I’ve done for you” “tries to create guilt rather than simply asking for a call”. That is Subtext on one draft, and the three assistants were not part of the example.
Two: they normalise things you did on purpose
All three correct fragments, repetition, unusual punctuation, hedging and dialect, including when those were choices. Asking for “voice preservation” doesn’t fix it (the 2026 studies are in my piece on rewording a message without making it sound like a robot wrote it), because the model has no way of knowing which oddities are yours and which are mistakes.
Related, and more subtle, is semantic inflation. A model turns “I might not make it” into “I won’t be able to make it,” or “you seemed a bit off” into “you were upset.” Each edit reads as more confident and is less accurate, and in a message about a relationship, accuracy about degree is most of the content.
Three: they write in a dialect people recognise
Every model has verbal habits. Writers have been cataloguing them for a while now, and once you can see them you can’t stop.
| Pattern | Examples | What it costs |
|---|---|---|
| Abstract nouns | testament, tapestry, beacon, cacophony | Swaps a concrete detail for a grand one |
| Binary framing | “It wasn’t X, it was Y” / “Not out of A, but B” | Imposes a neat conclusion on something messy |
| Stated interiority | “couldn’t help but feel,” “from a place of” | Names the emotion instead of showing it |
| Triadic lists | Three items where two would do | Reads as composed rather than written |
| Balanced antithesis | Two clauses of equal weight, endlessly | Rhythm that belongs to no human |
There’s a broader concern behind the vocabulary list. Studies of AI-assisted writing find that model intervention pushes different writers toward the same dominant patterns, which means the more you use these tools the more everyone’s writing converges.6 In a CHI 2025 study, 118 people in India and the United States wrote about their own lives, and with AI suggestions switched on, the Indian participants’ writing drifted toward Western styles.7 For a message whose entire purpose is being unmistakably from you, that is the wrong direction.
Four: the recipient may notice, and it costs you
This is the part people underestimate. There’s a research programme on what’s called AI-mediated communication, and its central finding is uncomfortable. People are unreliable at identifying AI-written text8, and they lean on flawed cues when they try. But when they believe text was AI-generated, they trust the writer less.9
So the risk of a generic rewrite goes past a mediocre message, to one that reads as insincere at the exact moment sincerity is the entire payload. An apology that trips someone’s AI detector does more damage than the clumsy apology you would have written yourself.
Five: they don’t know who you’re texting
Unless memory or a project carries something over, each session starts close to empty. To get a good draft you’d have to explain a decade of a friendship, what happened in March, why the phrase “it’s fine” means something specific between you two. Almost nobody does that, so the model writes for a generic recipient. Formality is what you get when a system knows nothing about the relationship, which is why the output so often sounds like customer service. That blank start is why Subtext reads the thread you paste or screenshot, and asks who a message is for when a draft pushes back on someone. It is also why Subtext has Memory. You can save the people you write to most, each with short notes on how you write to them, and typing @ in the composer opens the list of your people and styles.
There’s also the part people mention quietly. Pasting a screenshot of an argument, or a breakup draft, or a message about your family into a general-purpose chatbot feels different from asking it to debug code. That instinct isn’t paranoid.
What novelists did about all this
What follows is what convinced me this gap is real, and not something I invented to have something to sell.
Fiction writers hit these exact failures first, at higher stakes and higher volume. They kept using the models, just not raw. A whole layer of tooling grew up on top, including environments like Novelcrafter10, which lets you build a dictionary of banned clichés that it flags in red as text generates, and run targeted operations like “show, don’t tell” on a highlighted selection. Sudowrite11 does something similar with dedicated passes that convert summary into concrete sensory detail.
Serious users go further and run multi-model pipelines. One model for developmental notes and subtext analysis, a second for line edits under strict constraints, a filtering pass to scrub AI vocabulary, then a human pass to put the voice back.
That’s four tools and a checklist to revise one chapter. It works. It also tells you that the general models don’t do this job unassisted, and that the people who care most about the output have already accepted it.
Now apply that to a text message. Nobody is running a four-stage pipeline before replying to their sister. The need for a refined layer is identical and the tolerance for effort is roughly zero, which is the actual product problem. I looked separately at whether AI message rewriters actually work on messages like that.
What a more refined tool has to do differently
Three things, and none of them are “write better.”
Analyse before rewriting. Name what the draft is signalling before touching a word of it, the way an AI message checker should, including the part the writer didn’t intend. It also helps with sycophancy, because a tool that leads with a read commits to it before it has a chance to agree with you. That doesn’t make the read correct. Subtext runs on the same kind of model, so push it the way you’d push a friend. Which words support that read, and how else could they land?
Show the distance, don’t hide it. A version close to what you wrote, sitting next to a version written from scratch, is more useful than one polished replacement. You can see what changed and decide whether you’re willing to sound like that.
Read the relationship as well as the message. Who this person is to you, what the thread shows you’ve already tried, what “it’s fine” means in this specific friendship.
Those three things are what I’m building, so treat the rest of this section accordingly. Subtext tags the emotion in what you wrote before it suggests anything, which is a deliberately annoying design choice, because the moment it’s most useful is the moment you least want to hear it.
Illustrative, not captured output
it’s fine, i get it, you’re busy. i’ll stop asking.
What you’d send. Reads as withdrawal, and “I’ll stop asking” is a threat wearing an apology.
Hi, I completely understand things have been busy lately. No worries at all about tonight, just let me know whenever works better and we’ll sort something out.
A generic rewrite. Grammatical, pleasant, and it has deleted the fact that you’re hurt, which was the only information in the original.
it’s fine. i’m a bit disappointed though. i’d rather say that than pretend it’s nothing.
Same voice, keeps the hurt, drops the threat, and adds nothing you didn’t say.
The third thing, the relationship, is what Memory holds. Every note on a saved person can be read, edited or deleted, and a note stays until you delete it.
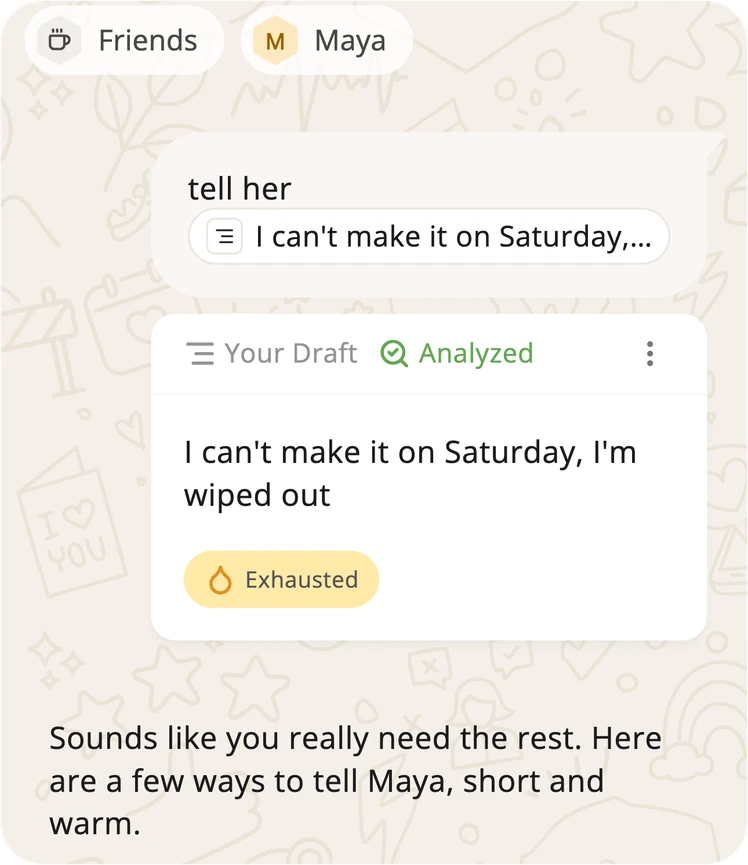
How the versions differ shows when the same sentence goes to two saved people. For this, two profiles were put into Memory on a test account: a best friend called Maya, whose notes include “Jokes land well, sarcasm does not.”, with the usual style Friends, and a manager called Jonas, whose notes include “Keep it brief and factual.”, with the usual style Work. The people are made up. What the app wrote back is not.
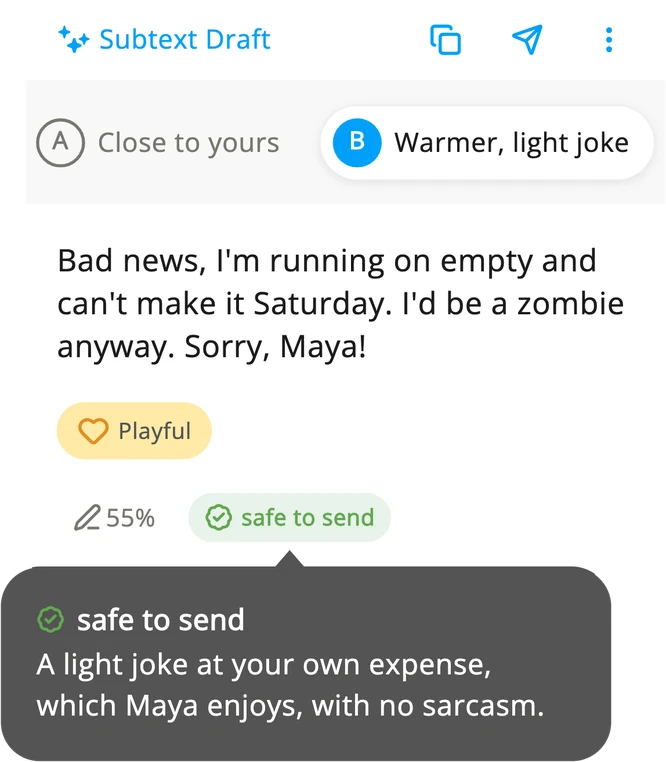
With Friends and Maya chosen above the conversation, the request was “tell her I can’t make it on Saturday, I’m wiped out”. Subtext took “I can’t make it on Saturday, I’m wiped out” as the draft and offered three versions. The first reads “I can’t make it on Saturday, I’m completely wiped out. Sorry!” The second reads “Bad news, I’m running on empty and can’t make it Saturday. I’d be a zombie anyway. Sorry, Maya!”, and the note behind its safe to send badge says “A light joke at your own expense, which Maya enjoys, with no sarcasm.”
With Work and Jonas chosen, the request was “tell him I can’t make it on Saturday, I’m wiped out”. The first version reads “I can’t make it on Saturday. I’m completely wiped out and need to rest.”, and its note says “Leads with the news and gives a short honest reason. Brief and factual, which suits a message to your manager.”
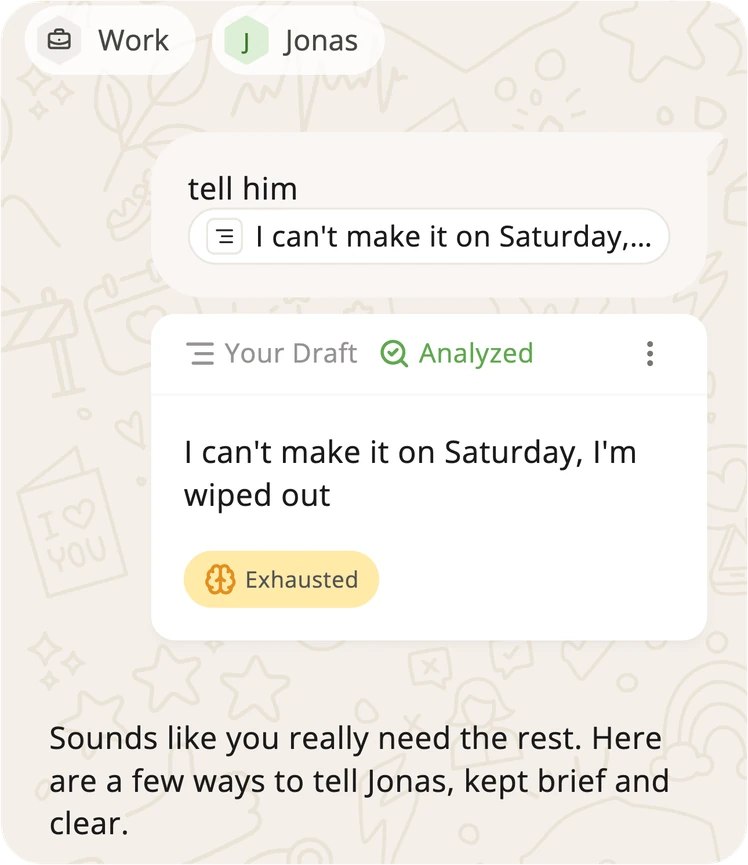
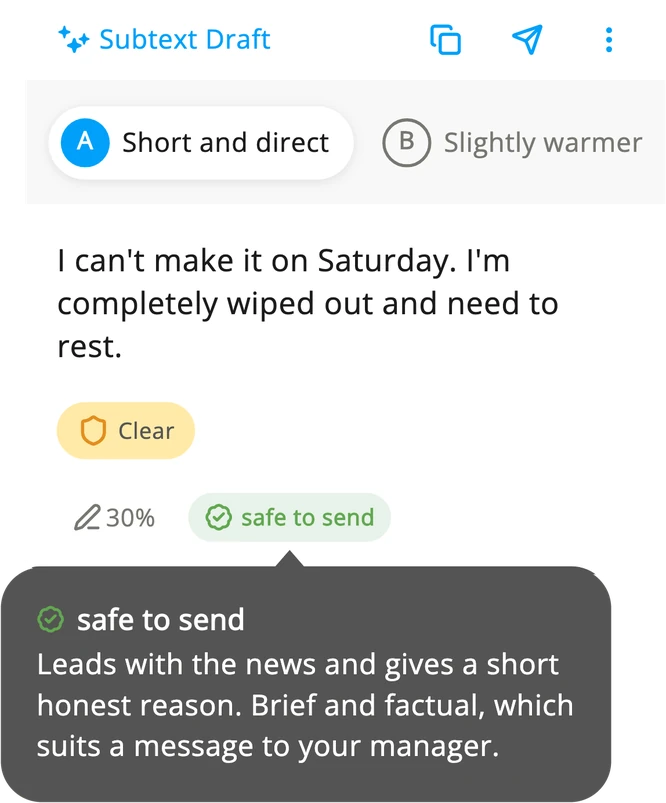
The Work style says “No exclamation marks.”, and none of the three versions for Jonas has one, while two of the three for Maya do. That fits the note and does not prove the note caused it. In both examples the third version added an offer nobody had asked for, to catch up soon for Maya and to hand things over for Jonas, and Subtext said so itself, for Maya with “The last one suggests catching up soon, which you didn’t say, so drop it if you’d rather not.” Both first versions also turned “wiped out” into “completely wiped out”, the change of degree this article calls semantic inflation, and neither note mentions it. Two examples are an illustration and not a test.
Venting first works too, and it is the case where a general chatbot needs instructions it never asks for. In one example, with a client and a project made up for it, the message to Subtext was not a draft but a vent under a client’s cheerful email: “ok honestly I’m frustrated. third call with Lea and the tracking is STILL broken”, followed by the fact that she is lovely, that they are raising money in November, that she is redesigning the store page instead, and a request for a recap “without sounding like I’m lecturing her”. Subtext named the feeling as Frustrated, wrote “I have a few quick questions so the recap lands as support and not a lecture.” and asked four: what the call covered, what exactly was needed “before Thursday”, how to frame the investor angle, and anything else to say.
Reply to... Lea Brandt, 14:12: Hi! Thanks so much for today, super helpful. We still couldn't get the install tracking to work, so we just made a new ad account. Also already working on a new design for the store page! Talk Thursday :)
ok honestly I'm frustrated. third call with Lea and the tracking is STILL broken, I told her twice it's a ten minute fix for her developer. she's lovely and they're raising money in november so I want to keep this going, but without tracking the numbers we show investors are useless. and now she's redesigning the store page instead. I need to send her a recap of today and get the tracking fixed before thursday without sounding like I'm lecturing her
That's a frustrating spot, especially when you like her and the investor timeline is real. I have a few quick questions so the recap lands as support and not a lecture.
- What did you actually cover on today's call that belongs in the recap? Ad account setup, Next steps for Thursday
- What exactly do you need from her before Thursday? Dev fixes tracking tomorrow
- How do you want to frame the investor angle? Investor numbers in November
- Anything else you want to say or ask her that she hasn't brought up? The store page redesign can wait until tracking works
Thanks, that gives me what I need. Here are a few ways to recap and get the tracking moving without it sounding like a lecture.
- Short and direct (Clear, safe to send): Thanks Lea, good session today. Quick recap: we set up the new ad account, and for Thursday we'll pick up from there. One ask: could your developer get the install tracking fixed tomorrow? That way we'll have clean numbers to build on for the November investor conversations. The store page redesign sounds exciting and I'd love to look at it once tracking is live. Clear ask with a specific day, and the redesign is parked as "once tracking is live" rather than criticized. Should land as practical and friendly.
- Warm, investor-focused (Supportive, heads-up): Thanks Lea, I enjoyed today! Recap: the new ad account is set up, and Thursday is for next steps. The one thing that would help me most is getting install tracking working tomorrow with your developer. It's a small fix, and it means the numbers you show investors in November will be solid. Happy to jump on a quick call with your developer if that makes it easier. The new store page can wait a few days until tracking is in, so we can see how it performs. Ties the fix to her own goal and offers help, which keeps it supportive. The call offer to the developer is something you never said, so check you're happy with it.
- Rewrite: collaborative plan (Collaborative, safe to send): Thanks Lea, glad it was useful, and good call getting the new ad account up so quickly. Here's where I think we landed: ad account is ready, and Thursday we'll go through next steps. To make the most of it, it would be great if your developer could fix the install tracking tomorrow. Then Thursday we'd be looking at real data, and by November you'd have numbers that make the investor story much stronger. I'm excited about the new store page too, and it will be even easier to judge once we can measure what it does. Let me know if anything's blocking the tracking fix. Opens with appreciation, frames tracking as what makes the redesign and the investor numbers work, and ends with an offer to unblock. Reads as partnership, not pressure.
I put "tomorrow" in as the fix date since you said the dev can do it then, and the second draft adds an offer to call the developer, which you didn't mention. Want it shorter, warmer, or a bit more confident?
With the answers in, its first version, “Short and direct”, reads “Thanks Lea, good session today. Quick recap: we set up the new ad account, and for Thursday we’ll pick up from there. One ask: could your developer get the install tracking fixed tomorrow? That way we’ll have clean numbers to build on for the November investor conversations. The store page redesign sounds exciting and I’d love to look at it once tracking is live.” The frustration stayed in the vent. The ask has a day attached, the reason is hers rather than yours, and the redesign is parked instead of criticised. Another version added an offer to call her developer, and Subtext flagged that as something “you didn’t mention”.
In practice, you paste the draft, or screenshot the thread so Subtext reads both sides, and it names what your message is about to signal before offering versions that still sound like you. Try Subtext in your browserDownload on the App StoreGet it on Google PlayScan it with your phone camera to install.
Where I’d still open ChatGPT
Long documents. Professional email. Anything where being correct matters more than being recognisably you. Research, first drafts, translation, and the specific mercy of getting words on an empty page when you can’t start.
And a fact that cuts against my own argument, which I’d rather include than leave out. A study of medical questions from a public forum12 found this.
The finding Evaluators preferred chatbot answers to physician answers in 78.6% of comparisons, and rated the chatbot’s responses empathetic or very empathetic at nearly ten times the rate.
These models can produce text that reads as warm, and that capability is real.
What they rarely do unprompted is tell you that your message reads like an ultimatum. They’ll make the ultimatum flow better and compliment you on your emotional honesty. That gap is small and it’s most of the job, and I built Subtext to close it. It names what your message reads like before it rewrites a single word of it.
A note on model versions. Everything above describes behaviour that has held across several generations of each model family, which is why I’ve mostly avoided naming specific versions. These systems change every few months and any post that pins its argument to one release number is wrong by winter.
Think I’ve been unfair to your favourite model? Tell me on LinkedIn.
Samet Durgun is the co-founder of Subtext, an app that catches the emotional tone of your messages and rewrites them in your own voice. He’s based in Berlin.
Sources
Every link above goes to the primary source where one exists.
- OpenAI, “Introducing Canvas,” 3 October 2024.
- Park et al., “MultiPragEval: Multilingual Pragmatic Evaluation of Large Language Models,” 2024. Tested English, German, Korean and Chinese across Gricean categories; Gemini was excluded for API access reasons at the time.
- OpenAI, “Sycophancy in GPT-4o: what happened and what we’re doing about it,” 29 April 2025.
- OpenAI, “Expanding on what we missed with sycophancy,” 2 May 2025.
- Sharma et al., “Towards Understanding Sycophancy in Language Models,” Anthropic, arXiv:2310.13548, October 2023.
- Research on stylistic homogenisation in AI-assisted writing, including Padmakumar and He, “Does Writing with Language Models Reduce Content Diversity?”, ICLR 2024, and Doshi and Hauser, “Generative AI enhances individual creativity but reduces the collective diversity of novel content,” Science Advances, 2024.
- Agarwal, Naaman and Vashistha, “AI Suggestions Homogenize Writing Toward Western Styles and Diminish Cultural Nuances,” CHI 2025.
- Jakesch, Hancock and Naaman, “Human heuristics for AI-generated language are flawed,” PNAS, 2023.
- Jakesch, French, Ma, Hancock and Naaman, “AI-Mediated Communication: How the Perception that Profile Text was Written by AI Affects Trustworthiness,” CHI 2019. See also Hancock, Naaman and Levy, “AI-Mediated Communication: Definition, Research Agenda, and Ethical Considerations,” Journal of Computer-Mediated Communication, 2020.
- Novelcrafter, Codex and text-replacement prompt features.
- Sudowrite, “Show, Don’t Tell” and Describe features.
- Ayers et al., “Comparing Physician and Artificial Intelligence Chatbot Responses to Patient Questions Posted to a Public Social Media Forum,” JAMA Internal Medicine, 28 April 2023. 585 evaluations; chatbot responses preferred in 78.6% and rated empathetic or very empathetic at 9.8 times the rate of physician responses.